Meta has updated its commercial terms and, according to a report by Nieman Lab picked up by The Verge, the new text could allow it to crawl business and media websites to train its artificial intelligence without the need for a prior licensing agreement. The terms go into effect on October 30.
The issue is significant because it affects any business page on Facebook, Instagram, WhatsApp, or Messenger, including media outlets that use these platforms to promote their content. The company denies that there are fundamental changes, but legal experts consulted warn of a much broader margin for interpretation.
What Meta’s clause says
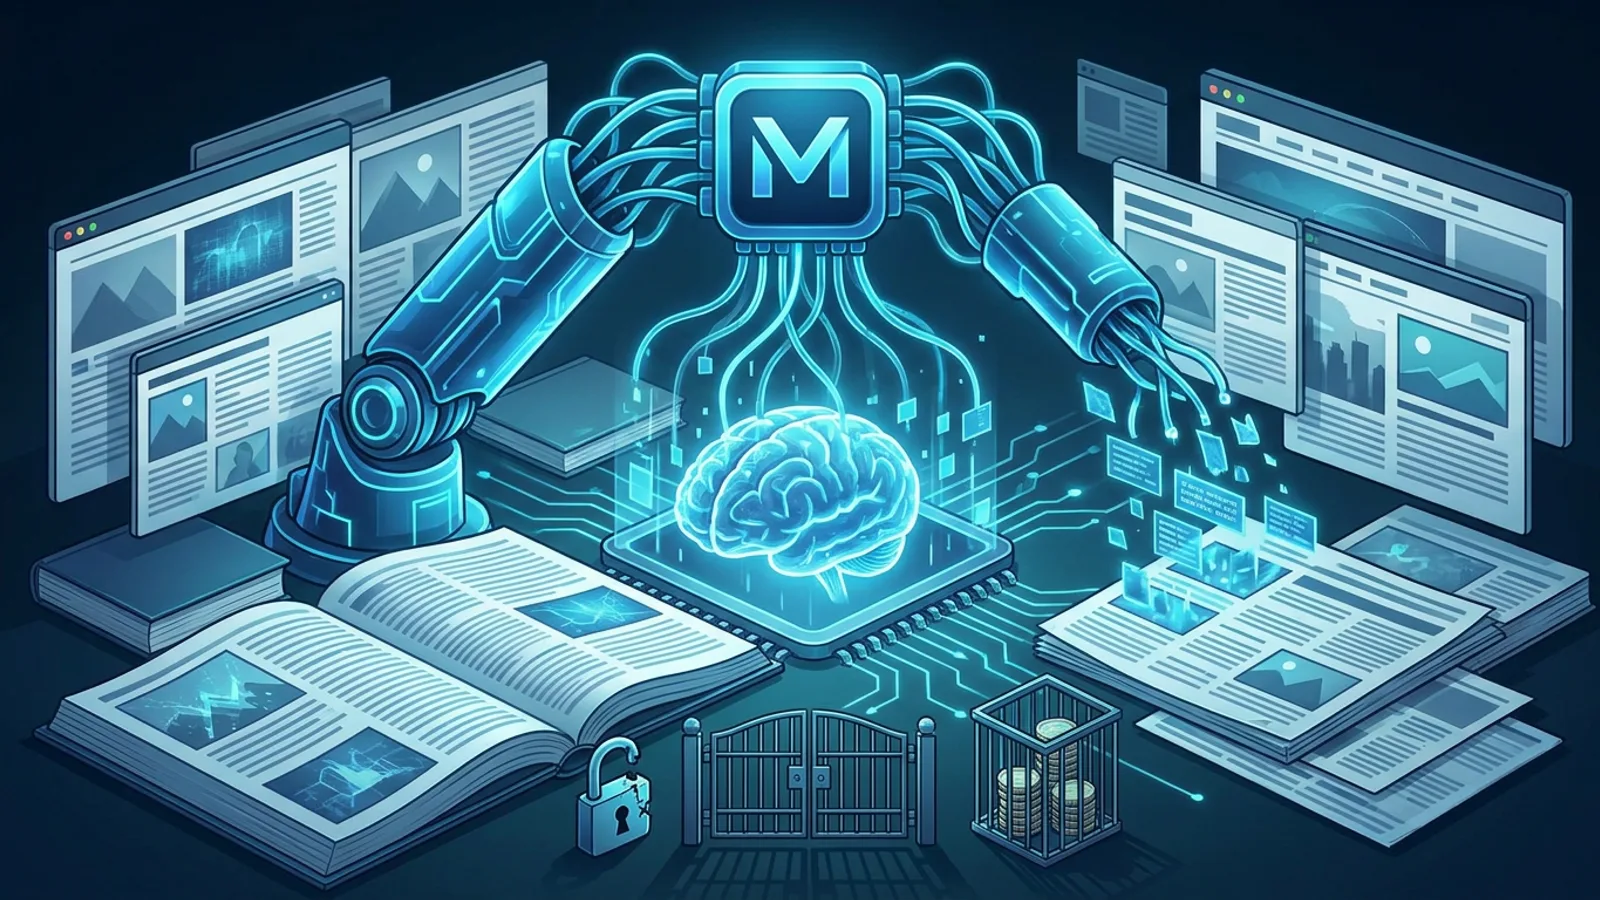
The new text authorizes Meta, or any entity acting on its behalf, to use automated tools such as crawlers, bots, or web spiders to access, index, cache, analyze, and collect domains, pages, or URLs "associated" with each client's products or services.
This authorization also extends to addresses accessible through the use that both the client and their users make of Meta's products. The company also reserves the possibility of creating test credentials and extracting updates periodically.
The use of the content is not limited to advertising purposes. According to the text, Meta may use it to "provide, develop, improve, research, train, and maintain the integrity" of its products and services.
Who it affects: Facebook, Instagram, WhatsApp, and Messenger
The policy reaches business accounts that promote content on Facebook, Instagram, WhatsApp, and Messenger. Any media outlet that invests in ads to attract readers or manages a business page falls within the perimeter of these terms.
The text also includes a direct warning: those who do not accept the policy may lose access to Meta's products for business or commercial purposes. In practice, rejecting the terms means giving up the advertising tool.
Meta’s version versus the legal experts’ reading
Daniel Roberts, a spokesperson for Meta, maintains that the company is only consolidating its commercial and self-service ad terms. According to his response, there is no change in how Meta uses web crawlers, and any suggestion to the contrary would be false. Roberts adds that content owners can continue to use the robots.txt file to mark their preferences.
Andy Stone, Meta's vice president of communications, posted on X that the update seeks to obtain accurate information about products for sale on third-party websites in order to improve ad and content recommendations on the platform. Stone clarified that the goal is not to crawl news sites.
The legal experts cited by Nieman Lab offer a different reading. According to the outlet, the terms could lead Meta to argue that its commercial clauses prevail over other blocking instructions, such as each site's own robots.txt file.
The role of the robots.txt file
The robots.txt is the mechanism with which a website indicates to crawlers which content can be read. Until now, it has been the main defense for publishers against the use of their texts to train AI models. If a commercial contract with Meta could outweigh that file, that barrier would lose much of its practical effect.
James Grimmelmann, a professor of digital and information law at Cornell, summarizes it to Nieman Lab by noting that, for news publishers, the text represents permission for Meta to train its AI with any content from their sites and, possibly, deploy some of that content even in competition with the media outlets themselves.
An example of the risk for publishers
The problem is better understood with a practical case. A regional newspaper buys ads on Instagram to promote a paid report. With the new clause, Meta could crawl the newspaper's entire domain, not just that specific piece, and use it to train its models, even if that media outlet had expressly blocked other crawlers via robots.txt.
The contrast with already signed licensing agreements
Meta has already followed OpenAI's path by closing content licensing agreements for AI with CNN, Fox News, USA Today, and People Inc. In those cases, the company pays to access specific material negotiated in advance with each media outlet.
The new commercial terms could give it access to a much larger volume of content without going through that type of negotiation, which is especially concerning for publishers who do not have their own agreement with Meta.
Meta One and charging for linking content
Last month, Meta launched the Meta One subscription, which forces businesses and creators to pay to include links in posts and reels. Nieman Lab highlights that Meta has started charging users to post links to the same content that, according to the new terms, it could crawl for free.
The combination has a direct economic effect: a publisher pays to link their own content, accepts terms that allow it to be crawled to train AI, and, if they reject them, loses commercial access to the platform.
What to review before October 30
Those who manage a website with a commercial presence on Meta can check several points derived from the new terms:
Read the full text of the commercial terms, paying attention to the clause regarding domains "associated" with products or services.
Review your own robots.txt file. Meta claims it continues to respect it, but the legal experts consulted warn that the company could argue that its commercial terms prevail over it.
Consult with legal counsel if there is a licensing agreement with another AI company that could conflict with Meta's new terms.
Assess which domains are linked to business accounts, as the clause applies to those associated with the promoted products or services.
What this means in practice
If a media outlet or business advertises on Facebook, Instagram, WhatsApp, or Messenger, accepting the terms that go into effect on October 30 may imply ceding to Meta the reading of its website to train artificial intelligence. Rejecting them, on the other hand, may mean losing access to the platform's commercial tools.
Meta insists that there are no real changes and that the goal is to improve ad recommendations. The legal experts cited by Nieman Lab consider the text to be broad enough to go beyond that explanation. As long as there is no written clarification limiting that scope, what the signed contract says prevails.
Frequently asked questions
When do Meta’s new terms go into effect?
Meta's new commercial terms go into effect on October 30.
Who exactly do these terms affect?
They affect business accounts that promote content on Facebook, Instagram, WhatsApp, and Messenger, including media outlets that use these platforms to advertise their content.
Does Meta acknowledge that it will crawl media websites to train its AI?
No. Meta, through its spokesperson Daniel Roberts, maintains that there is no change in how it uses its web crawlers and that it is only consolidating existing commercial terms.
Does the robots.txt file still protect a website’s content from Meta?
Meta claims it respects robots.txt tags, but legal experts cited by Nieman Lab warn that the company could argue that its commercial terms prevail over that file.
What happens if a company rejects the new terms?
According to Meta's own text, those who do not accept the policy may lose access to the company's products for business or commercial purposes.
Does Meta already pay some media outlets for using their content in AI?
Yes. Meta has content licensing agreements for AI with CNN, Fox News, USA Today, and People Inc, in which it pays for specific material negotiated in advance.
What is the relationship between this and Meta One?
Meta One is a subscription launched last month that forces businesses and creators to pay to include links in posts and reels, while the new terms could allow it to crawl that same content at no additional cost.